Machine learning operations (MLOps) have evolved from being a niche practice to becoming an essential pillar in AI-driven enterprises. The integration of large language models (LLMs) into MLOps is proving to be a game-changer, helping businesses manage and optimize their machine learning (ML) lifecycle.
Understanding MLOps
MLOps, or Machine Learning Operations, is a set of practices designed to automate and streamline the ML lifecycle. It brings together data science, DevOps, and machine learning to ensure the continuous delivery and integration of ML models. Key stages of MLOps include data preparation, model training, deployment, and monitoring.
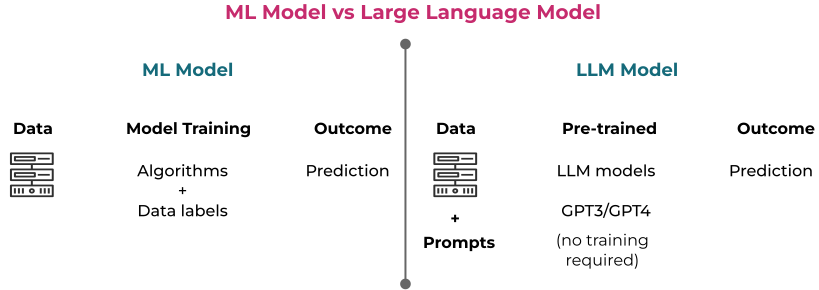
Traditionally, these operations can be complex, requiring manual intervention at several stages. However, the rise of large language models (LLMs), like GPT-4 or OpenAI's Codex, is enabling the automation of these tasks, reducing the cognitive load on teams and ensuring greater precision.
The Role of LLMs in MLOps: An Overview
LLMs are highly capable neural networks trained on vast amounts of text data. They excel in generating human-like text and solving complex language tasks, but their utility extends far beyond NLP. By integrating LLMs into MLOps, enterprises can automate, optimize, and scale their operations.
LLMs can enhance multiple stages of the ML pipeline by automating data pre-processing, transforming raw data into formats ready for model training. They also assist with feature engineering by suggesting relevant features, streamline model deployment by automatically configuring cloud or on-premises setups, and improve monitoring by detecting model drift and recommending retraining options to maintain performance.
Automating Data Processing Using LLMs
LLMs significantly simplify data processing by automating steps like data cleaning, transformation, normalization, and augmentation. They utilize techniques like natural language understanding (NLU) to comprehend and clean unstructured text data, while named entity recognition (NER) helps in extracting relevant entities from the text. Once cleaned, LLMs convert this data into structured formats using vectorization techniques like embeddings (e.g., BERT, word2vec), making it ready for machine learning models. By automating these repetitive tasks, LLMs improve data consistency and reduce manual intervention, leading to more efficient workflows.
For example, in a sentiment analysis task for customer reviews, LLMs can automatically clean messy text, correcting abbreviations like "u" to "you" and fixing punctuation errors. They can extract important entities, such as product names, and convert the cleaned data into embeddings, creating structured datasets that are directly usable in training sentiment models. This removes the need for manual data cleaning, drastically speeding up the preparation process while ensuring higher accuracy in downstream analysis.
Efficient Feature Engineering with LLMs
Feature engineering involves transforming raw data into meaningful input variables for machine learning models, and LLMs excel at automating this process. They use word embeddings, which convert words into numerical vectors that capture semantic relationships, and pattern recognition algorithms to identify hidden correlations in the data and suggest relevant features. LLMs also perform normalization, adjusting data to a common scale, and dimensionality reduction using PCA (Principal Component Analysis), which reduces the number of input variables while retaining important information. This automation helps uncover novel features, improving model performance without the need for manual intervention.
In insurance risk modeling, LLMs process unstructured customer feedback, identifying key patterns like frequent mentions of "speeding" or "accidents" and correlate these behaviors with past claim data. The model can then generate a feature such as "risk score based on driving behavior keywords," which adds predictive power to the risk assessment model. This automatic generation of new features helps the insurance company better predict customer risk profiles with higher accuracy.
LLMs in Model Deployment: Streamlining the Process
Model deployment requires configuring environments, managing dependencies, and ensuring models run optimally in production. LLMs can automate many of these tasks by generating deployment scripts tailored to specific environments. Using environment detection algorithms, LLMs identify the system’s requirements (cloud, on-premises, edge) and create corresponding configurations, like Dockerfiles or Kubernetes manifests. They also handle dependency management, ensuring the right versions of libraries are installed. Furthermore, LLMs optimize resource allocation and auto-scaling policies, adjusting the infrastructure based on real-time performance data to ensure efficiency.
For example, in a multicloud deployment, LLMs can automatically generate scripts for different cloud platforms (AWS, Google Cloud, Azure), each tailored to the platform’s infrastructure. They handle the setup of necessary dependencies, configure the scaling of computational resources based on traffic patterns, and monitor the deployment for errors, ensuring seamless deployment across multiple environments. This reduces the complexity and time involved in deploying models, making it faster and less prone to human errors.
Enhancing Model Monitoring and Maintenance with LLMs
Once a model is deployed, continuous monitoring is essential to maintain its performance. LLMs help automate this by tracking model inputs and outputs in real-time, using anomaly detection algorithms to spot performance degradation or data drift. They can compare model predictions with actual outcomes, flagging deviations that might indicate the need for retraining. LLMs can also trigger automated retraining workflows, pulling in fresh data and retraining the model to keep it aligned with the changing data distributions. Additionally, LLMs can provide insights on hyperparameter tuning or suggest improvements in the feature set to optimize the model further.
In financial modeling, where market conditions change rapidly, LLMs continuously monitor the predictions of a trading algorithm. If a model's predictions start deviating from actual market outcomes, the LLM detects these anomalies and can either trigger an automatic retraining process or alert the data science team. This ensures the model stays up to date with evolving market conditions, reducing the risk of significant financial loss due to outdated predictions.
Integrating LLMs into MLOps offers several key benefits, including automation of repetitive tasks, allowing engineers to focus on high-impact work, and improved scalability by managing large datasets and automating pipelines. This integration reduces human errors by handling tasks like data cleaning, feature engineering, and deployment. Additionally, LLMs accelerate the entire ML lifecycle, leading to faster time-to-market for models, while facilitating continuous learning by identifying opportunities for retraining, ensuring models stay relevant in dynamic environments.
The integration of LLMs into MLOps is not just an incremental improvement—it's a paradigm shift. By leveraging the power of LLMs, organizations can optimize their ML pipelines, reduce manual overhead, and accelerate the deployment of high-performance models. Despite the challenges, the benefits of LLM-enhanced MLOps are clear, from faster time-to-market to more accurate, scalable, and resilient machine learning systems.